apyhub
Back

Convert Speech to Text with (Whisper Large-v3)

What it does

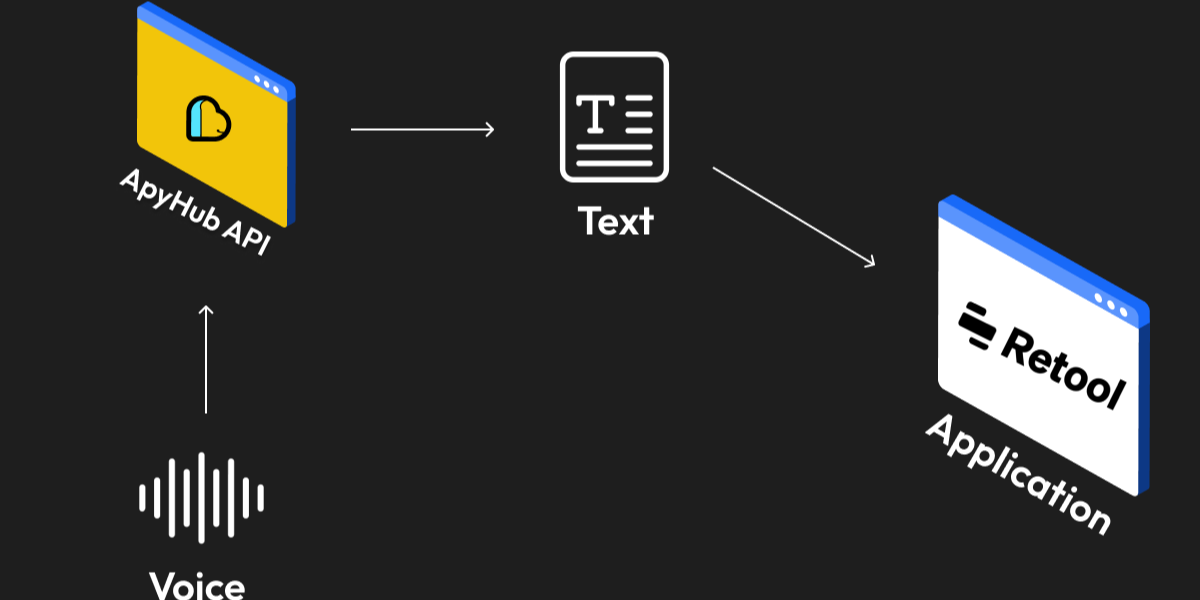
Whisper Speech to Text transcribes speech in an audio file using OpenAI Whisper large-v3. Upload a WAV, MP3, M4A, or other common audio file as the file field of a multipart/form-data request, and the transcript comes back in a single synchronous call. There are no job IDs and no polling.

The response is a small JSON object with three fields. text holds the transcript, or an empty string when no speech is found. language is the auto-detected language as an ISO 639-1 code, such as en. duration is the length of the input audio in seconds, which is useful for logging usage or checking what was processed.

Use it for voice notes, call and meeting transcription, subtitle drafts, podcast and video indexing, voice-driven search, and any workflow that needs recorded speech as searchable text. Language detection is automatic, so you don't need to know the spoken language in advance.

A file that can't be decoded as audio returns 400, and a request without a file field returns 422.

Note: Runs OpenAI Whisper large-v3 (faster-whisper) on a dedicated NVIDIA RTX 5080 GPU. Response time scales with audio length: a few seconds for short clips and around 8 seconds for a one-minute recording.

POST
Transcribe audio to text
https://api.eu.apyhub.com/mastera-ai/whisper-speech-to-text/v1/whisper/transcribe

QUICKSTART

GUIDE

Quickstart

curl -X POST "https://api.eu.apyhub.com/mastera-ai/whisper-speech-to-text/v1/whisper/transcribe" \
  -H "apy-token: $APY_TOKEN" \
  -F "[email protected]"

What you'll get back

{
  "text": "The quick brown fox jumps over the lazy dog. This is an audit test recording.",
  "language": "en",
  "duration": 5.92
}
TRY ITLIVE · 425 ATOMS
Loading your default key…
The full key is used to call the gateway and stays in this tab — never sent to orbit or saved.
Max 100MB total per request (all files combined). Larger? Use this API's URL-based endpoint instead, if it has one.
Audio file to transcribe (WAV, MP3, M4A and most common formats). Maximum file size: 10 MB.

About this endpoint

What it does

Transcribes speech in an audio file to text using OpenAI Whisper large-v3 (faster-whisper backend). Upload a WAV, MP3, M4A or other common audio file as multipart/form-data and get back the transcript, the auto-detected language and the audio's duration in one synchronous call — no polling, no task ID.

Request Body

ParameterTypeMandatoryDescription
fileFileYesAudio file to transcribe (WAV, MP3, M4A and most common formats). Maximum file size: 10 MB.

Response

The response is a single JSON object with three fields.

FieldTypeDescription
textStringThe transcribed text. Empty string when no speech is found.
languageStringAuto-detected language as an ISO 639-1 code, e.g. en, el.
durationNumberLength of the input audio in seconds, e.g. 5.92. This is audio length, not processing time.

Notes

  • Response time scales with audio length: a few seconds for short clips, around 8 seconds for a one-minute recording.
  • A file that cannot be decoded as audio returns 400 with "Invalid or corrupted audio file — could not decode audio data". A request without a file field returns 422.

Max 100MB total per request (all files combined). Larger? Use this API's URL-based endpoint instead, if it has one.

▣ COMMON ERRORS

Errors any endpoint can return

400bad_request

Required parameter missing or malformed body.

401unauthorized

API key missing, revoked, or not authorized for this service.

429rate_limited

Your plan's per-second rate exceeded. Retry with exponential backoff.

503upstream_busy

Backend temporarily unavailable. Try again in a few seconds.